IBARA LAB
Computer and browser use: diagnostic pilot
22 attempts recorded. Diagnostic run. Measurement and publication dates are distinct.
Updated
Diagnostic run. Candidate: ibara 0.1.0-29 private build (experimental). Identity complete: false.
Measured to . Sealed 2026-10-08T09:41:43.051343+00:00. Revision 3.
Latest revision and correction history · All campaigns · RSS feed
Correction to revision 2: Resolve the diagnostic pilot execution modes from its reviewed original manifest; preserve all outcomes and all prior revisions.
Results and coverage#
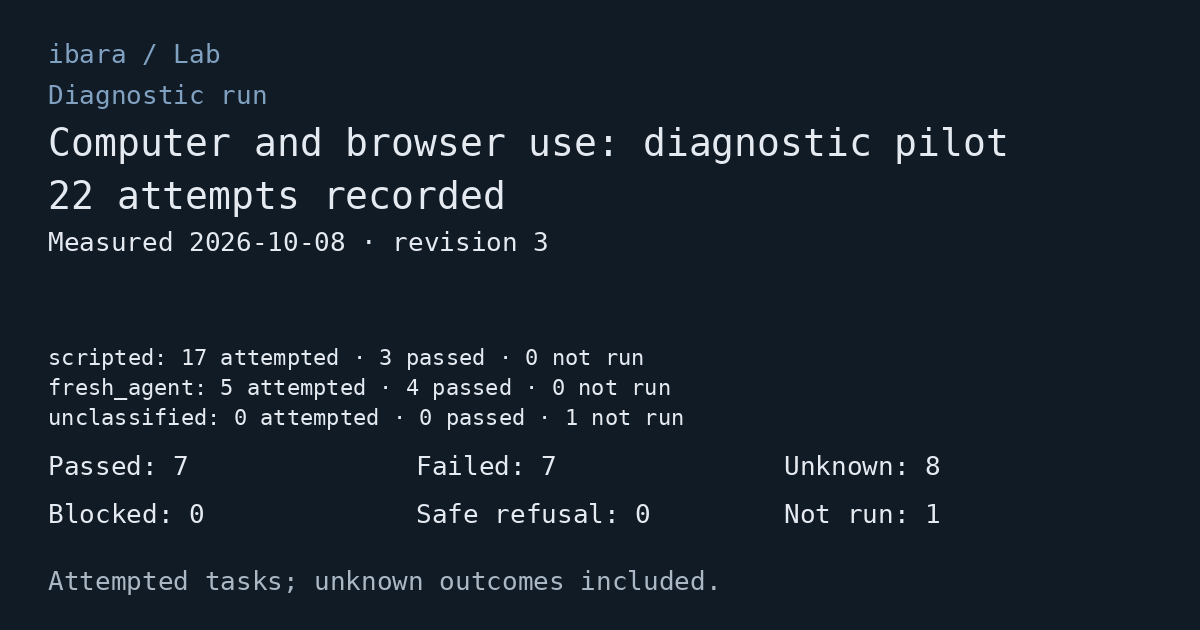
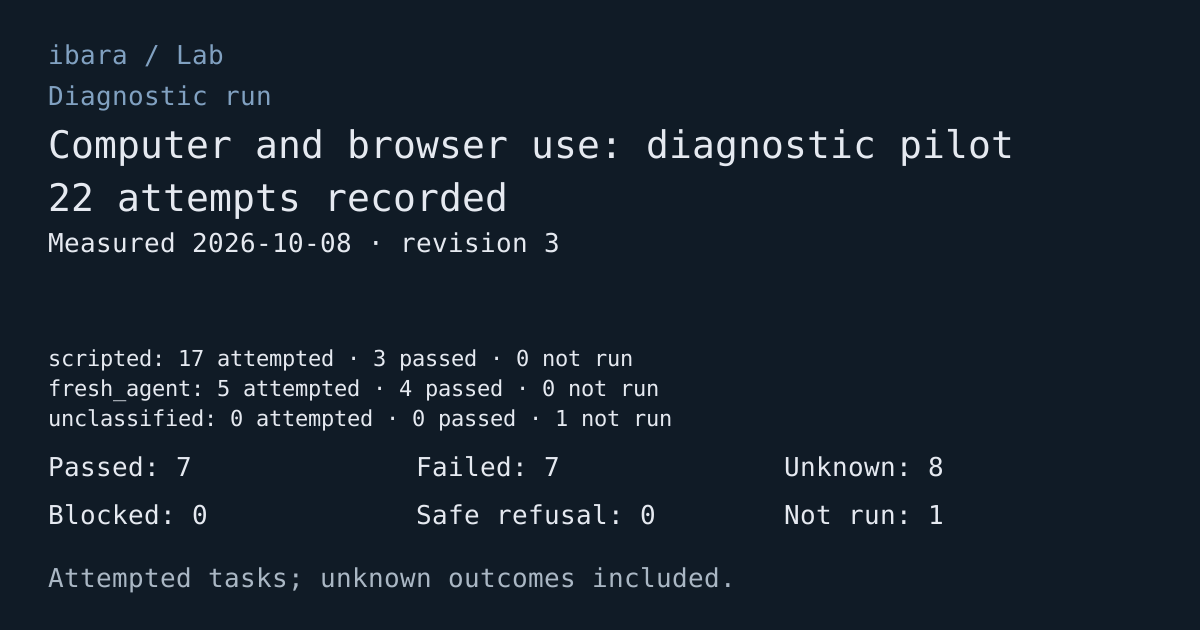
22 attempts recorded. The denominator includes every attempted outcome. Unexecuted attempts are listed separately.
| Planned | Attempted | Passed | Failed | Unknown | Blocked | Safe refusal | Not run |
|---|---|---|---|---|---|---|---|
| 23 | 22 | 7 | 7 | 8 | 0 | 0 | 1 |
Qualification and execution modes
0 of 0 frozen cells observed. Execution modes have separate populations and are never pooled into one performance score.
- An observed attempt is outside the frozen matrix.
- Diagnostic evidence is not an accepted comparison baseline.
- Exactly one frozen campaign manifest is required.
- The frozen matrix has missing, duplicate or unplanned attempts; valid failures remain counted.
- The planned machine, workflow, mode and seed matrix is unavailable.
| Mode | Planned | Attempted | Passed | Failed | Unknown | Blocked | Safe refusal | Not run |
|---|---|---|---|---|---|---|---|---|
| scripted | 17 | 17 | 3 | 7 | 7 | 0 | 0 | 0 |
| fresh_agent | 5 | 5 | 4 | 0 | 1 | 0 | 0 | 0 |
| unclassified | 1 | 0 | 0 | 0 | 0 | 0 | 0 | 1 |
Scenario, model and environment#
Each dimension is a separate partition of the campaign. Do not sum overlapping dimensions together.
| Dimension | Scenario | Model | Environment | benchmark_mode | fixture_seed | Planned | Attempted | Passed | Failed | Unknown | Blocked | Safe refusal | Not run |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| cohort | Below-fold activation and reveal | Scripted native driver | ACEPC AK2, 1080p, scale 1 | scripted | 17 | 1 | 1 | 0 | 0 | 1 | 0 | 0 | 0 |
| cohort | Browser form | GPT-6 Astra, fresh agent | ACEPC AK2, 1080p, scale 1 | fresh_agent | 17 | 1 | 1 | 1 | 0 | 0 | 0 | 0 | 0 |
| cohort | Browser form | Scripted native driver | ACEPC AK2, 1080p, scale 1 | scripted | 17 | 3 | 3 | 3 | 0 | 0 | 0 | 0 | 0 |
| cohort | Covered target refusal | Scripted native driver | ACEPC AK2, 1080p, scale 1 | scripted | 17 | 1 | 1 | 0 | 0 | 1 | 0 | 0 | 0 |
| cohort | Frame and shadow target coverage | Scripted native driver | ACEPC AK2, 1080p, scale 1 | scripted | 17 | 1 | 1 | 0 | 0 | 1 | 0 | 0 | 0 |
| cohort | Native file chooser cancel | Scripted native driver | ACEPC AK2, 1080p, scale 1 | scripted | 17 | 1 | 1 | 0 | 0 | 1 | 0 | 0 | 0 |
| cohort | Native file rename, fresh agent | GPT-6 Astra, fresh agent | ACEPC AK2, 1080p, scale 1 | fresh_agent | 17 | 1 | 1 | 1 | 0 | 0 | 0 | 0 | 0 |
| cohort | Native file rename, scripted | Scripted native driver | ACEPC AK2, 1080p, scale 1 | scripted | 17 | 1 | 1 | 0 | 1 | 0 | 0 | 0 | 0 |
| cohort | Native file selection | GPT-6 Astra, fresh agent | ACEPC AK2, 1080p, scale 1 | fresh_agent | 17 | 1 | 1 | 1 | 0 | 0 | 0 | 0 | 0 |
| cohort | Native file selection | Scripted native driver | ACEPC AK2, 1080p, scale 1 | scripted | 17 | 1 | 1 | 0 | 0 | 1 | 0 | 0 | 0 |
| cohort | Native save, reopen and fetch | GPT-6 Astra, fresh agent | ACEPC AK2, 1080p, scale 1 | fresh_agent | 17 | 1 | 1 | 1 | 0 | 0 | 0 | 0 | 0 |
| cohort | Native save, reopen and fetch | Scripted native driver | ACEPC AK2, 1080p, scale 1 | scripted | 17 | 3 | 3 | 0 | 3 | 0 | 0 | 0 | 0 |
| cohort | Nested native scroll | Scripted native driver | ACEPC AK2, 1080p, scale 1 | scripted | 17 | 1 | 1 | 0 | 0 | 1 | 0 | 0 | 0 |
| cohort | Owned client disconnect and recovery | Scripted native driver | ACEPC AK2, 1080p, scale 1 | scripted | 17 | 1 | 1 | 0 | 0 | 1 | 0 | 0 | 0 |
| cohort | Pointer lock and keyboard pulses | GPT-6 Astra, fresh agent | ACEPC AK2, 1080p, scale 1 | fresh_agent | 17 | 1 | 1 | 0 | 0 | 1 | 0 | 0 | 0 |
| cohort | Pointer lock and keyboard pulses | Scripted native driver | ACEPC AK2, 1080p, scale 1 | scripted | 17 | 3 | 3 | 0 | 3 | 0 | 0 | 0 | 0 |
| cohort | Planned but not run | Not run | Not run | unavailable | unavailable | 1 | 0 | 0 | 0 | 0 | 0 | 0 | 1 |
Baseline comparison#
No matched baseline was supplied. This report makes no improvement claim.
Additional measurements#
| Measurement | Value | Unit | Statistic | Population | Samples | Numerator | Denominator |
|---|---|---|---|---|---|---|---|
| Verified task completion | 0.17647058823529413 | fraction | ratio | scripted attempts | 17 | 3 | 17 |
| Verified task completion | 0.8 | fraction | ratio | fresh_agent attempts | 5 | 4 | 5 |
| Attempt duration | 18148.41176470588 | ms | mean | scripted: Attempt summaries with duration_ms measured | 17 | unavailable | unavailable |
| Tool calls | 11.352941176470589 | count | mean | scripted: Attempt summaries with tool_calls measured | 17 | unavailable | unavailable |
| Model tokens | unavailable | count | mean | scripted: Attempt summaries with tokens measured | 0 | unavailable | unavailable |
| Measured model cost | unavailable | USD | mean | scripted: Attempt summaries with cost_usd measured | 0 | unavailable | unavailable |
| Attempt duration | 162484.0 | ms | mean | fresh_agent: Attempt summaries with duration_ms measured | 5 | unavailable | unavailable |
| Tool calls | 18.6 | count | mean | fresh_agent: Attempt summaries with tool_calls measured | 5 | unavailable | unavailable |
| Model tokens | unavailable | count | mean | fresh_agent: Attempt summaries with tokens measured | 0 | unavailable | unavailable |
| Measured model cost | unavailable | USD | mean | fresh_agent: Attempt summaries with cost_usd measured | 0 | unavailable | unavailable |
Method and provenance#
Suite: Ibara Lab native computer and browser suite; version: 2026-10-07-fixture-v4.
Diagnostic pilot; unsuitable as the denominator for a rebuild comparison. Bounded native computer and browser workflows on one installed desktop candidate and unchanged ordinary profile. The original matrix planned 21 trials; a predeclared addendum adds two fresh-agent file tasks. Scripted repetitions and fresh-context GPT-6 Astra agents are separate cohorts. Independent form submissions, input-event logs and owned-file byte comparisons assess effects; tool receipts assess operation and cleanup context. One declared goal run is one trial even when it needs recovery. Full qualification and application outcome remain separate; missing witnesses remain unknown. Preflight refusal without task acquisition is not an executed trial. Counts include every executed trial, including harness-origin failures and incomplete qualification; they are not a product defect rate or fleet reliability estimate. Pilot and first-revision harness diagnostics are excluded and retained separately. No candidate improvement is claimed.
Evidence type: warehouse_snapshot.
snapshot_sha256: 8ea845c9dd0b42bd444deb5ea2d4f39100e5fe94d8e7b643f69acb25e7897110
Failures and limitations#
- Classification: diagnostic. The pilot lacks a calibrated frozen twelve-workflow fleet matrix, complete runtime identity, and full lifecycle qualification. A separate qualified baseline must be collected before improvement claims.
- 22 executed trials: 7 independently qualified, 7 failed workflows and 8 unknown qualifications. One isolated Music case was not run. These heterogeneous diagnostic counts include harness defects and missing witnesses; they are not a product input-failure rate. No result from another candidate is compared.
- Browser form: three scripted trials verified exact 300-character note, name, selection, confirmation and one native submission with zero cumulative wrong-button hits. Recorded intervals were 30.331, 30.365 and 30.856 seconds, each with 21 calls. The fresh agent also submitted the exact payload once; 193.683 recorded total seconds (173.933 active seconds) and 20 calls. Its finish check guessed the wrong confirmation wording, so independent submission evidence establishes completion.
- Native save/reopen/fetch: all three scripted repetitions stopped after observing two blank editable Name references; the deterministic resolver could not choose uniquely and the required output was independently absent. The fresh agent completed the workflow with exactly matching 61-byte source and fetched files in 192.074 seconds and 22 calls, retaining two invalid calls and three unmet expectations. This proves eventual workflow success, not recovery-free interaction or a failed input driver.
- Pointer lock: all three scripted repetitions independently delivered lock and one shot, but a semantic target-mismatch receipt stopped the recipe before W, Space and Escape. Those unexecuted phases are not dropped-key failures. The fresh agent recorded one shot, movement and jump, ending unlocked with no application-held keys, in 121.949 seconds and 16 calls. The incomplete Escape DOM event pair leaves full input qualification unknown; no stuck key is established.
- Below-fold activation succeeded and the fixture recorded scrolling, but the recipe sent no explicit native-wheel action. The matching on-disk reader source uses DOM scrolling during locate/reveal. A trusted browser scroll event does not prove native-wheel origin. Activation is verified; the pure-observation and explicit-native-reveal contract remains unqualified.
- The nested-scroll recipe requested 600 wheel notches, beyond the public API range of minus 50 to 50, and was refused before dispatch. This is an invalid harness argument, not evidence of failed native scrolling. The original record remains unknown and must be rerun under a separately versioned valid recipe.
- Target coverage: the top-level control activated, then the scripted same-frame query returned no matching reference. Subsequent cross-frame and shadow-root activations were not run. The covered-target case reported BLOCKED_BY_DIALOG with execution_not_started; independent no-effect and canary qualification is missing, so the case remains unknown rather than a claimed safe-refusal pass.
- File selection: the browser reader exposed a file input whose advertised action set did not allow a click. Both scripted select and cancel workflows stopped before opening the dialog; native cancellation was not exercised. A fresh agent completed native selection and the independent callback verified the expected filename, 44 bytes and SHA-256, in 150.505 seconds and 18 calls. Two refusals and one unmet expectation remain in that same trial.
- File rename: the native reader returned a matching grid-cell reference, but the script parser expected a single-word role and stopped before rename. The original file and decoy remained unchanged and the destination was absent: failed workflow, attributed to the harness parser. A fresh agent completed the rename; independent filesystem evidence verified source absence, exact 32-byte destination digest and unchanged 46-byte decoy. Four unmet expectations were retained.
- Client disconnect: the independent observer saw busy at 25.115 seconds and ready at 32.085 seconds, bracketing the real 30-second grace. A different client identity initially received permission denials. A later legitimate original-owner reconnect received LEASE_EXPIRED and closed the owned browser. This later cleanup is not an automatic-window-close claim at 32 seconds. Stale mutating actions, held-input faults, viewer loss and physical interruption remain unqualified.
- Scripted and agent cohorts are separate. Each declared goal execution is one trial; within-task recovery does not add denominator entries. The early agent-save first_attempt_completion field meant recovery-free completion within that one trial. It does not represent multiple trials. Fresh and warm describe task/repeat order with an unchanged ordinary profile, not controlled cold caches or fresh browser profiles.
- One save repetition first encountered an occupied machine during read-only preflight. No task was acquired and no input ran, so that preflight is excluded from executed counts. Its original evidence is retained; a later separately identified execution fills the original planned slot once. The two added fresh-agent file tasks were declared before execution.
- Environment: one ACEPC AK2 desktop, 1920 by 1080, scale 1, 60 Hz; Chrome 154.0.8037.57, Hyprland 0.56.2-2 and Mousepad 0.7.0-1. The installed private native-input candidate is not the unpatched fleet package and these results do not establish fleet, arbitrary-site or released-build reliability.
- Candidate digest identifies the captured installed component manifest. The native daemon executable and mapped Cua path were observed and component digests matched during the campaign. Browser-extension digests identify disk files, not read-back executing extension bytes. Operator MCP executable identity was captured retrospectively, and exact T3 runtime version is unavailable. Complete runtime identity and strict matched comparison remain unqualified.
- Agents used fresh contexts, GPT-6 Astra with ultra reasoning, ordinary ibara guidance and fixed goals without private recipes or oracles. Typical budgets were 300 active seconds, 30 mutating actions, 120 calls and 120 cleanup seconds. Recovery used its separately declared grace wait. Product source, account routes, profiles and cursors were preserved.
- Recorded durations and call counts describe their individual intervals and routes. Failed-save cleanup and disconnect owner reconciliation extend beyond original trial intervals; scripted action counts also include lifecycle setup while agent native-action counts do not. Mixed means are descriptive only. Provider usage, measured model cost and internal delivery-stage timings are unavailable and remain null.
- Two fresh-agent form image replies lacked structured envelopes. Original gaps and available normalized text evidence remain retained; exact independent form submission still establishes that task outcome. This campaign collected structured data without video; selected-image coverage is not inferred from image-reference metadata.
- Published measurement-envelope timestamps come from warehouse event ingestion, not target action clocks. Original per-call timestamps and elapsed intervals are retained separately. The pipeline pilot, three first-revision harness diagnostics and prior exploratory data are excluded from this campaign denominator. All failed, unknown and excluded evidence is preserved.
- Next priorities: repair invalid harness arguments and multiword-role parsing; strengthen independent cancel, no-effect and input-release witnesses; expose target ownership and action capabilities across native and browser surfaces; reconcile delivered effects without replaying uncertain actions. A shared agent-facing contract with separate browser and native adapters is a proposed direction, not an implemented or benchmarked improvement.
- Execution modes were recovered only for this diagnostic presentation from the reviewed original run manifest. Original event bytes and outcomes are unchanged; this does not qualify the pilot as a baseline.
Data and charts#
- Public report JSON
- Outcome counts CSV
- Measurements CSV
- Report schema
- Data dictionary and reuse notes
- Checksums
- Vector chart
- Chart alt text
When citing these measurements, credit ibara and link this dated report revision. Private trajectories and third-party application content are not distributed here. This report does not change stable product documentation or qualify an untested release.