IBARA LAB
Six-task computer-use baseline with GPT-6.1 Sol
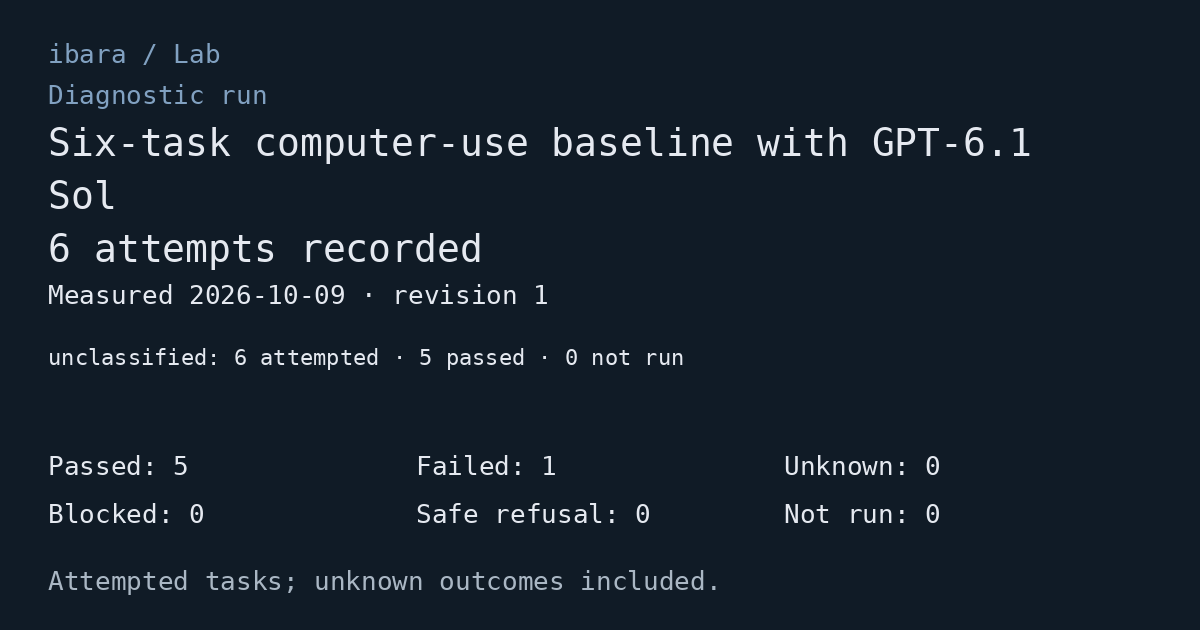
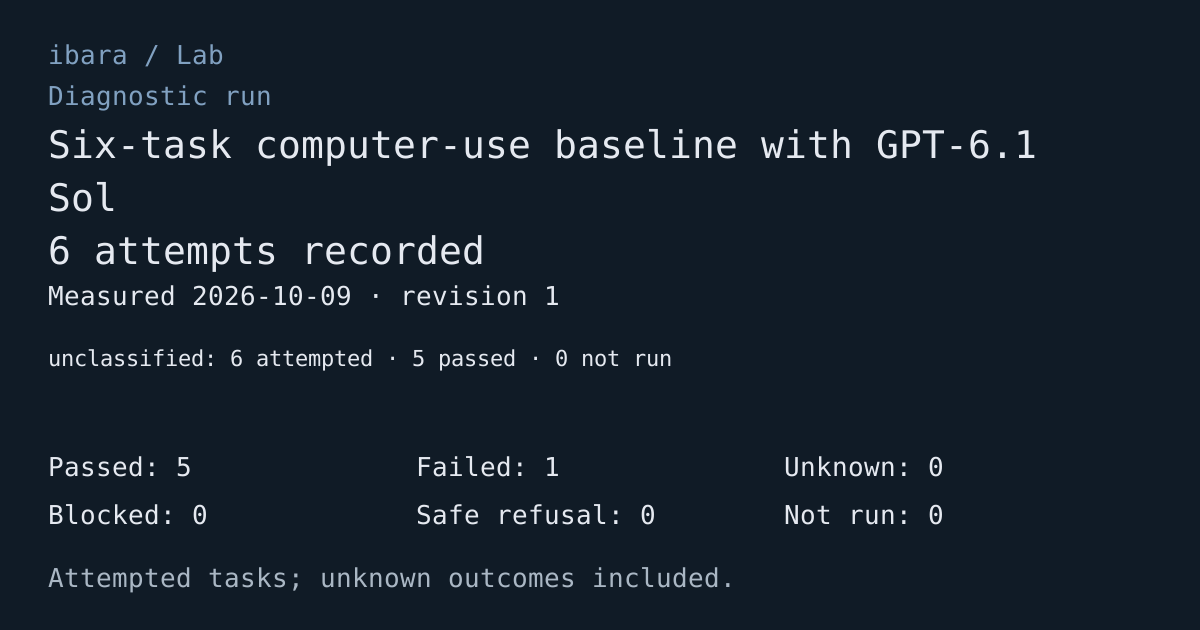
6 attempts recorded. Diagnostic run. Measurement and publication dates are distinct.
Updated
Diagnostic run. Candidate: Private Ibara v14 (experimental). Identity complete: false.
Measured to . Sealed 2026-10-09T02:11:43.536776+00:00. Revision 1.
Latest revision and correction history · All campaigns · RSS feed
Results and coverage#
6 attempts recorded. The denominator includes every attempted outcome. Unexecuted attempts are listed separately.
| Planned | Attempted | Passed | Failed | Unknown | Blocked | Safe refusal | Not run |
|---|---|---|---|---|---|---|---|
| 6 | 6 | 5 | 1 | 0 | 0 | 0 | 0 |
Qualification and execution modes
0 of 0 frozen cells observed. Execution modes have separate populations and are never pooled into one performance score.
- An observed attempt is outside the frozen matrix.
- Diagnostic evidence is not an accepted comparison baseline.
- Exactly one frozen campaign manifest is required.
- The frozen matrix has missing, duplicate or unplanned attempts; valid failures remain counted.
- The planned machine, workflow, mode and seed matrix is unavailable.
| Mode | Planned | Attempted | Passed | Failed | Unknown | Blocked | Safe refusal | Not run |
|---|---|---|---|---|---|---|---|---|
| unclassified | 6 | 6 | 5 | 1 | 0 | 0 | 0 | 0 |
Scenario, model and environment#
Each dimension is a separate partition of the campaign. Do not sum overlapping dimensions together.
| Dimension | Scenario | Model | Environment | benchmark_mode | fixture_seed | Planned | Attempted | Passed | Failed | Unknown | Blocked | Safe refusal | Not run |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| cohort | Browser form and validation | GPT-6.1 Sol, low reasoning | One Linux desktop, Chromium and native applications | unclassified | 17 | 1 | 1 | 0 | 1 | 0 | 0 | 0 | 0 |
| cohort | Download, edit and upload | GPT-6.1 Sol, low reasoning | One Linux desktop, Chromium and native applications | unclassified | 17 | 1 | 1 | 1 | 0 | 0 | 0 | 0 | 0 |
| cohort | Editor save, reopen and delivery | GPT-6.1 Sol, low reasoning | One Linux desktop, Chromium and native applications | unclassified | 17 | 1 | 1 | 1 | 0 | 0 | 0 | 0 | 0 |
| cohort | File manager move and rename | GPT-6.1 Sol, low reasoning | One Linux desktop, Chromium and native applications | unclassified | 17 | 1 | 1 | 1 | 0 | 0 | 0 | 0 | 0 |
| cohort | Native file picker and upload | GPT-6.1 Sol, low reasoning | One Linux desktop, Chromium and native applications | unclassified | 17 | 1 | 1 | 1 | 0 | 0 | 0 | 0 | 0 |
| cohort | Search and nested scrolling | GPT-6.1 Sol, low reasoning | One Linux desktop, Chromium and native applications | unclassified | 17 | 1 | 1 | 1 | 0 | 0 | 0 | 0 | 0 |
Baseline comparison#
No matched baseline was supplied. This report makes no improvement claim.
Additional measurements#
No additional measurements were supplied. Missing measurements are not zero.
Method and provenance#
Suite: Six everyday browser, desktop and mixed workflows; version: six-workflows-sol61-v1.
One GPT-6.1 Sol agent with low reasoning, one physical desktop, six tasks in fixed order and one attempt per task. The actor starts with a fresh context and shares that context across the six tasks. Task inputs use seed 17 of the existing synthetic workflows. Native Ibara input and browser read surfaces are allowed; backend actions and answer inspection are forbidden. Independent application events and file bytes establish outcomes. Cleanup is checked after every task. Target work budget is 120 seconds per task, with a 15-minute overall execution cap including cleanup. This is a small in-house baseline of the agent and Ibara together.
Evidence type: warehouse_snapshot.
snapshot_sha256: e261654bf60620798d652a388c7d0eab25d73e097e942bf37569409abc4890a0
Failures and limitations#
- Six single attempts are a practical snapshot, not a statistical reliability estimate or an external benchmark score.
- The earlier multi-machine Astra Ultra campaign is not a matched comparator. No improvement claim is made.
- Actor model and effort are bound to the accepted dispatch configuration. The delegation interface does not expose a separate child executable version, provider token usage or cost; these values are unavailable.
- Task durations include agent deliberation and tool waits. They are not isolated driver latency. Same-context task order must be preserved for a paired rerun.
- No video is recorded. Native response text and structured frames are retained; image bytes were not retained by this actor capture.
- The full fleet qualification matrix is outside this short run. A failed workflow is not by itself proof of an input-driver defect.
Data and charts#
- Public report JSON
- Outcome counts CSV
- Measurements CSV
- Report schema
- Data dictionary and reuse notes
- Checksums
- Vector chart
- Chart alt text
When citing these measurements, credit ibara and link this dated report revision. Private trajectories and third-party application content are not distributed here. This report does not change stable product documentation or qualify an untested release.